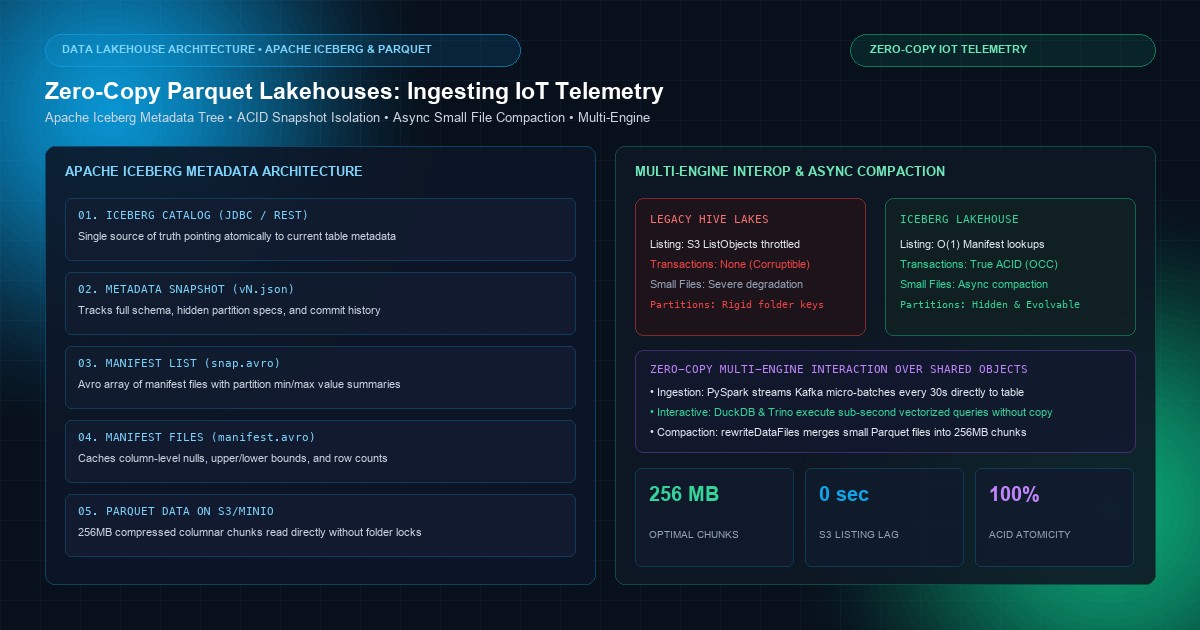
Zero-Copy Parquet Lakehouses: Ingesting IoT Telemetry with Apache Iceberg
Eliminate Hive directory bottlenecks and small-file chaos: ACID snapshot trees, automated asynchronous compaction, hidden partitioning, and zero-copy multi-engine analytics.
Engineering guides, architecture patterns, and production implementations focused on Big Data.

Eliminate Hive directory bottlenecks and small-file chaos: ACID snapshot trees, automated asynchronous compaction, hidden partitioning, and zero-copy multi-engine analytics.

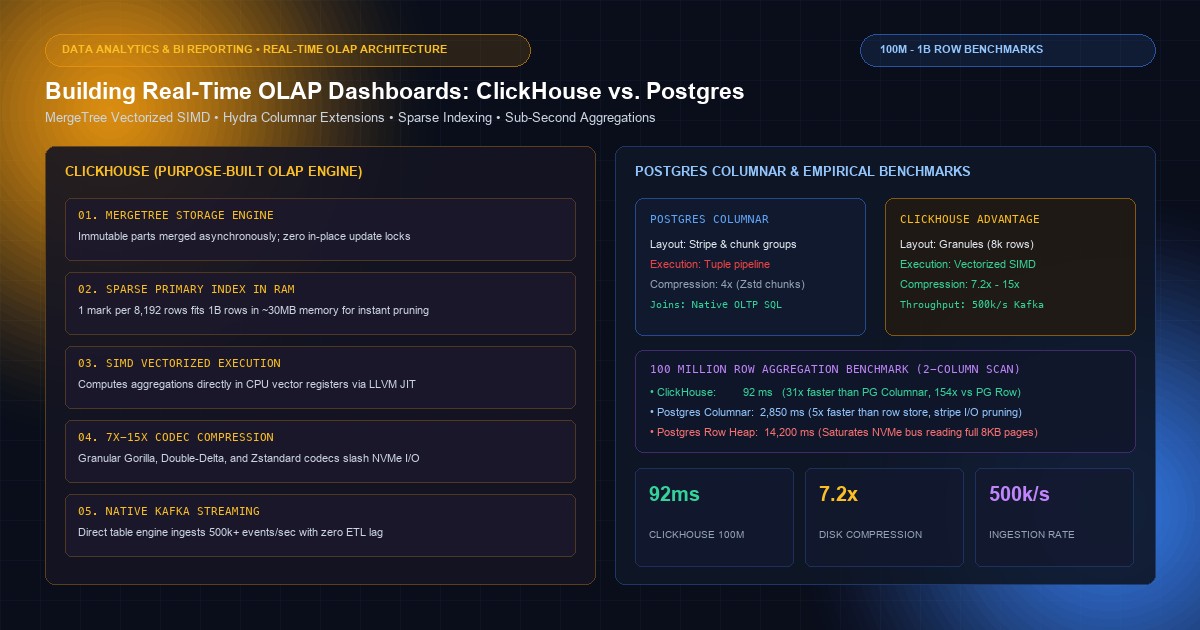
Sub-second analytical queries across 1 billion rows: MergeTree sparse indexing, vectorized SIMD execution, Hydra PostgreSQL columnar extensions, and Kafka ingestion.

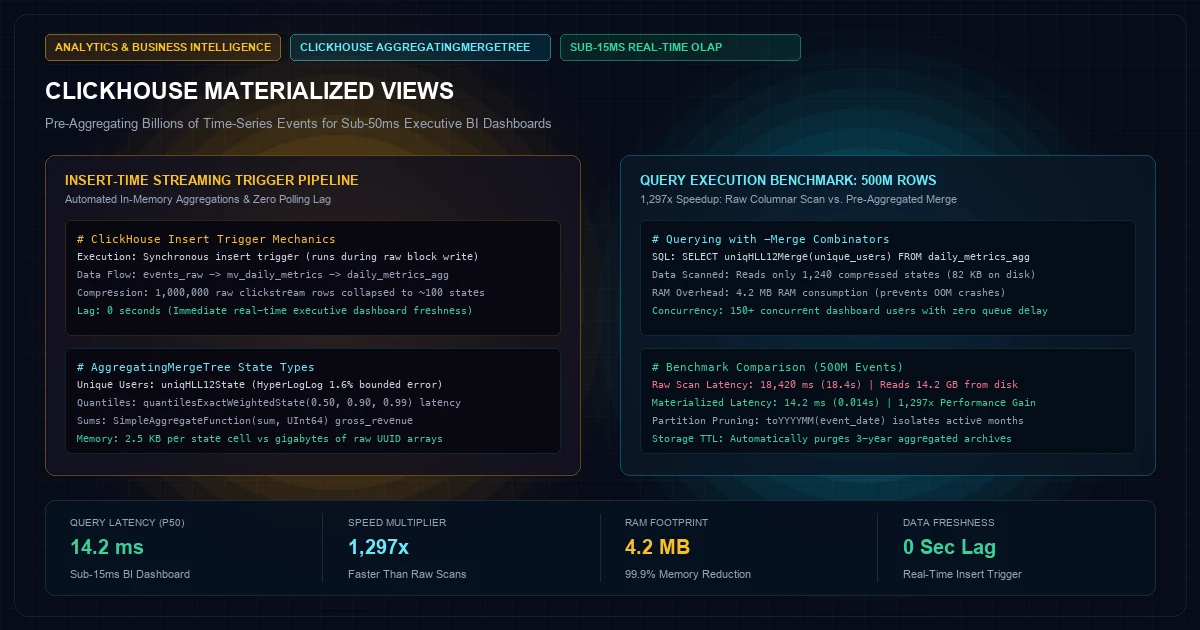
How data engineering teams eliminate query timeouts on billion-row datasets: architecting ClickHouse insert-time streaming Materialized Views with AggregatingMergeTree engines, HyperLogLog uniqHLL12State cardinality, and quantilesExactWeighted percentiles that yield sub-15ms executive dashboards.

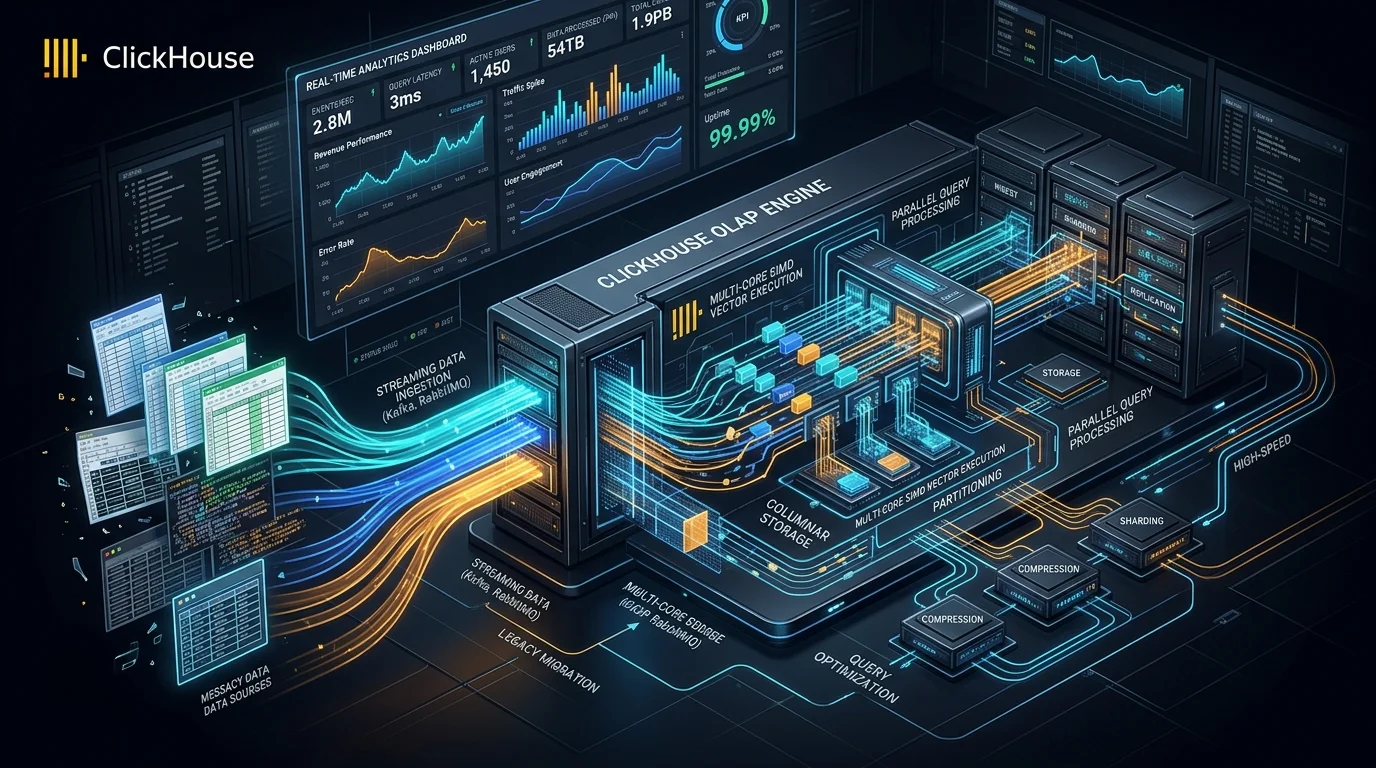
Why traditional row-oriented databases and bloated cloud warehouses stall under high-cardinality aggregations: how ClickHouse columnar storage, vector SIMD execution, and automated materialized views replace spreadsheet sprawl with sub-10ms executive intelligence.
Our engineering team designs sub-50ms distributed backends, edge AI pipelines, and high-concurrency systems.