Technical SEO Architecture for Next.js 14/15: Eliminating Crawl Budget Waste & SSR Bottlenecks
A deep systems engineering guide to building enterprise Next.js App Router applications for Googlebot: streaming XML sitemap segmentation, dynamic tag-based ISR revalidation, eliminating soft 404s, and solving hybrid SSR/RSC hydration latency.
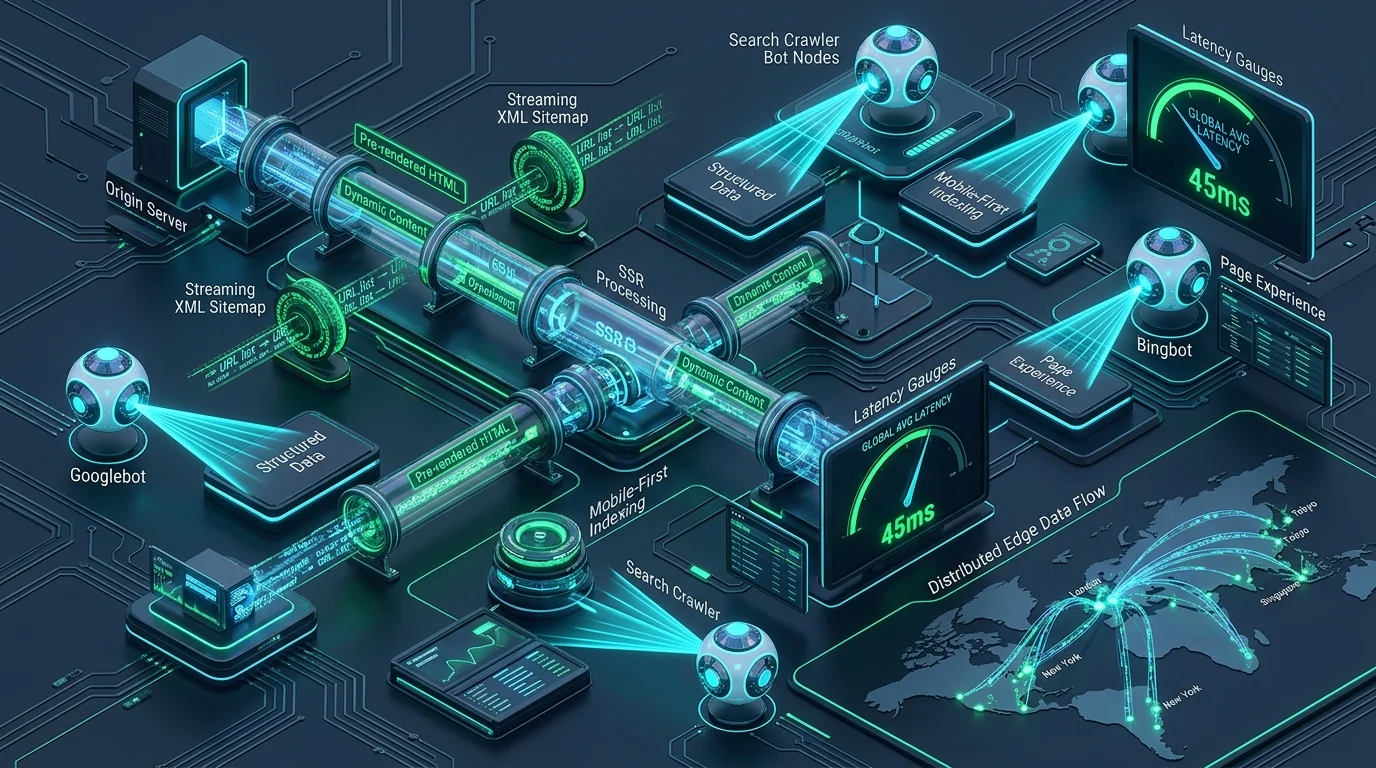
For years, frontend engineering teams celebrated the death of server-rendered monoliths. React, Vue, and single-page architectures promised instantaneous client-side transitions, component modularity, and rapid feature velocity.
Yet behind the scenes of high-growth eCommerce platforms, directories, and B2B SaaS hubs, growth and organic search teams watched in horror as indexation stalled. New catalog pages languished in Google Search Console under "Discovered – currently not indexed", crawl budgets evaporated on un-cacheable dynamic lambdas, and social media scrapers rendered blank white cards.
The arrival of the Next.js App Router (14/15) was pitched as the ultimate reconciliation between developer experience and SEO. By bringing React Server Components (RSC) into production, teams could deliver server-rendered HTML while retaining client-side reactivity.
However, moving to Next.js does not magically fix your technical SEO. In fact, without disciplined architecture, Next.js introduces new, subtle failure modes: inflated RSC flight payloads, memory-heavy XML sitemaps, soft-404 status leaks, and unstable Time-to-First-Byte (TTFB).
This guide provides the definitive systems blueprint for engineering Next.js web applications to dominate Googlebot crawling and Core Web Vitals.
1. The Anatomy of Modern Crawl Budget Waste
Googlebot does not browse the web like a human user on a MacBook Pro over fiber optic internet. Googlebot is a distributed, resource-constrained distributed crawler operating under a strict Crawl Budget per domain.
Crawl budget is determined by two factors:
- Crawl Demand: How important and frequently updated Google believes your URLs are.
- Crawl Rate Limit: How fast your origin server responds before Googlebot throttles requests to prevent crashing your database.
[ Googlebot Ingestion Pipeline ]
               │
        HTTP GET /product-slug
               │
      ┌────────┴────────┐
      ▼                 ▼
[ Fast SSR (<200ms) ]  [ Slow DB Query (>1500ms) ]
   ✅ Crawl Rate Expands   ⚠️ Googlebot Throttles Crawl Rate
   ✅ 10,000 pages/day     ❌ 500 pages/day ceiling
When Next.js dynamic routes query un-indexed PostgreSQL tables or execute heavy microservice calls during server rendering, TTFB climbs from $150\text{ms}$ to $1,800\text{ms}$. When Googlebot encounters average latencies above $1.0\text{s}$, its crawl scheduler automatically reduces request concurrency, leaving 80% of your long-tail product pages uncrawled.
2. Segmented Streaming Sitemaps for Scale (>50,000 URLs)
A common mistake in large Next.js deployments is generating a single monolithic sitemap.xml using an async database query fetching 40,000 rows.
This causes three critical failures:
- Node.js heap out-of-memory (OOM) crashes during static build step.
- Googlebot request timeouts when fetching the dynamic XML payload.
- Inability to pinpoint which category of URLs is failing indexation.
Next.js provides a native, type-safe API for sitemap segmentation via generateSitemaps():
// app/sitemap.ts - Scalable Chunked Sitemaps
import { MetadataRoute } from "next";const URLS_PER_SITEMAP = 10000;
const BASE_URL = "https://knetwork.live";
// Step 1: Tell Next.js how many sitemap chunks exist
export async function generateSitemaps() {
const totalProducts = await fetchProductCount(); // e.g., 45,000
const totalChunks = Math.ceil(totalProducts / URLS_PER_SITEMAP);
return Array.from({ length: totalChunks }, (_, id) => ({ id }));
}
// Step 2: Stream only the slice needed for the requested chunk id
export default async function sitemap({
id,
}: {
id: number;
}): Promise<MetadataRoute.Sitemap> {
const start = id URLS_PER_SITEMAP;
const products = await fetchProductSlice(start, URLS_PER_SITEMAP);
return products.map((item) => ({
url: ${BASE_URL}/catalog/${item.slug},
lastModified: new Date(item.updatedAt),
changeFrequency: "weekly",
priority: 0.8,
}));
}
This automatically compiles a sitemap index at /sitemap.xml referencing /sitemap/0.xml, /sitemap/1.xml, etc., allowing Googlebot to parallelize sitemap processing across independent threads.
3. Solving the SSR vs TTFB Dilemma: Tag-Based On-Demand ISR
Running pure server-side rendering (export const dynamic = "force-dynamic") guarantees fresh data, but destroys your TTFB and taxes your origin databases. Conversely, pure static exports (output: "export") prevent real-time updates.
The architectural sweet spot for enterprise SEO is Incremental Static Regeneration (ISR) with Cache Tags:
// lib/data/articles.ts
export async function getArticleBySlug(slug: string) {
  const res = await fetch(https://api.internal/articles/${slug}, {
    next: {
      tags: [article:${slug}, "articles"],
      revalidate: 86400, // 24-hour background fallback
    },
  });  if (!res.ok) return null;
  return res.json();
}
When your editorial team or automated CMS updates an article, dispatch a lightweight webhook hitting an administrative route handler that purges the exact cache tag:
// app/api/revalidate/route.ts
import { revalidateTag } from "next/cache";
import { NextRequest, NextResponse } from "next/server";export async function POST(request: NextRequest) {
  const secret = request.headers.get("x-revalidate-token");
  if (secret !== process.env.REVALIDATION_SECRET) {
    return NextResponse.json({ message: "Invalid token" }, { status: 401 });
  }  const { tag } = await request.json();
  revalidateTag(tag);  return NextResponse.json({ revalidated: true, now: Date.now() });
}
The Result: Googlebot and visitors receive pre-compiled, sub-50ms static HTML cached at the reverse proxy or CDN edge. The moment content changes, cache invalidation occurs instantly without rebuilding the entire application.
4. Eliminating the Ghost Soft-404 Disaster
A soft 404 occurs when a page that should return a 404 Not Found returns an HTTP 200 OK containing text such as "Sorry, item out of stock"* or a blank shell.
Google considers soft 404s a major indicator of poor site quality. In the App Router, developers often catch API errors and render an empty fallback state without altering the HTTP response header.
// ❌ WRONG: Emits HTTP 200 OK with empty content (Soft 404)
export default async function ProductPage({ params }: { params: { slug: string } }) {
  const product = await getProduct(params.slug);
  if (!product) {
    return <div>Product not found!</div>;
  }
  return <ProductView product={product} />;
}
// ✅ CORRECT: Instructs Next.js runtime to emit strict HTTP 404 header
import { notFound } from "next/navigation";export default async function ProductPage({ params }: { params: { slug: string } }) {
  const product = await getProduct(params.slug);
  if (!product) {
    notFound(); // Triggers app/not-found.tsx with actual 404 status
  }
  return <ProductView product={product} />;
}
By coupling notFound() with a custom app/not-found.tsx template, you ensure Googlebot immediately de-indexes decommissioned URLs without wasting crawl cycles.
5. Type-Safe Schema.org Injection
Search engines no longer rely solely on natural language processing to understand web entities. They ingest Schema.org structured data to generate Knowledge Graph entries, carousel cards, and FAQ accordions.
Instead of writing loose, untyped strings that break when schema definitions drift, enforce type safety using the schema-dts standard:
import { WithContext, TechArticle } from "schema-dts";export function generateTechArticleSchema(post: Post): WithContext<TechArticle> {
  return {
    "@context": "https://schema.org",
    "@type": "TechArticle",
    headline: post.title,
    description: post.excerpt,
    datePublished: post.publishedAt,
    dateModified: post.updatedAt,
    inLanguage: "en-US",
    author: {
      "@type": "Person",
      name: post.author.name,
      jobTitle: post.author.role,
      sameAs: [
        "https://github.com/mdanisurr",
        "https://knetwork.live"
      ],
    },
    publisher: {
      "@type": "Organization",
      name: "KNetwork Systems",
      url: "https://knetwork.live",
      logo: {
        "@type": "ImageObject",
        url: "https://knetwork.live/apple-icon.png",
      },
    },
  };
}
6. The 10-Point Production Next.js Technical SEO Checklist
Before pushing any enterprise Next.js App Router codebase to production:
| Check | Objective | Verification Command / Tool | |
|---|---|---|---|
| Canonical Headers | Prevent multi-parameter query duplicates | Verify rel="canonical" in <head> | |
| Single H1 Tag | Ensure distinct document topic hierarchy | Inspect DOM with automated linter | |
| Double Title Check | Prevent layout.tsx template concatenation | curl -s URL | grep "<title>" |
| Image Dimensions | Zero Cumulative Layout Shift (CLS) | Use next/image with width & height | |
| OpenGraph Alt Tags | Social card accessibility | Check og:image:alt metadata | |
| Sitemap Host Isolation | Zero cross-domain URLs in XML | Validate origin matching in sitemap.ts | |
| Hard 404 Status | Stop soft-404 crawl budget bleed | Check HTTP response status code | |
| Gzip / Brotli | Keep wire transfer payloads under 60KB | Test Accept-Encoding: gzip, br | |
| Robots Header | Disallow internal administrative APIs | Verify /robots.txt rules | |
| Author sameAs | Fulfill Google E-E-A-T evaluator standards | Inspect JSON-LD Person entity |
Frequently Asked Questions
Key questions answered regarding this architectural implementation.
Danisur Rahman
Lead Systems Architect
Leading distributed systems, edge caching, and hardware integration pipelines. Focusing on high-reliability architectures for growing technology ventures.
More From The Engineering Blog
View All Articles→Satellite NTN & 3GPP Release 18: Bridging Terrestrial Cellular and Orbital Direct-to-Device IoT
How 3GPP Release 17/18 standardized Direct-to-Device satellite connectivity, allowing standard NB-IoT modems with ordinary eSIMs to communicate with LEO constellations.
Smart City Infrastructure Physics: Acoustic Water Leak Detection & Radar Streetlighting
Why modern municipal IoT succeeds by prioritizing utility physics over citizen surveillance—slashing non-revenue water loss by 22% and lighting power by 58%.
Enjoyed this technical breakdown?
Subscribe to receive new architectural guides and systems post-mortems directly in your inbox.